
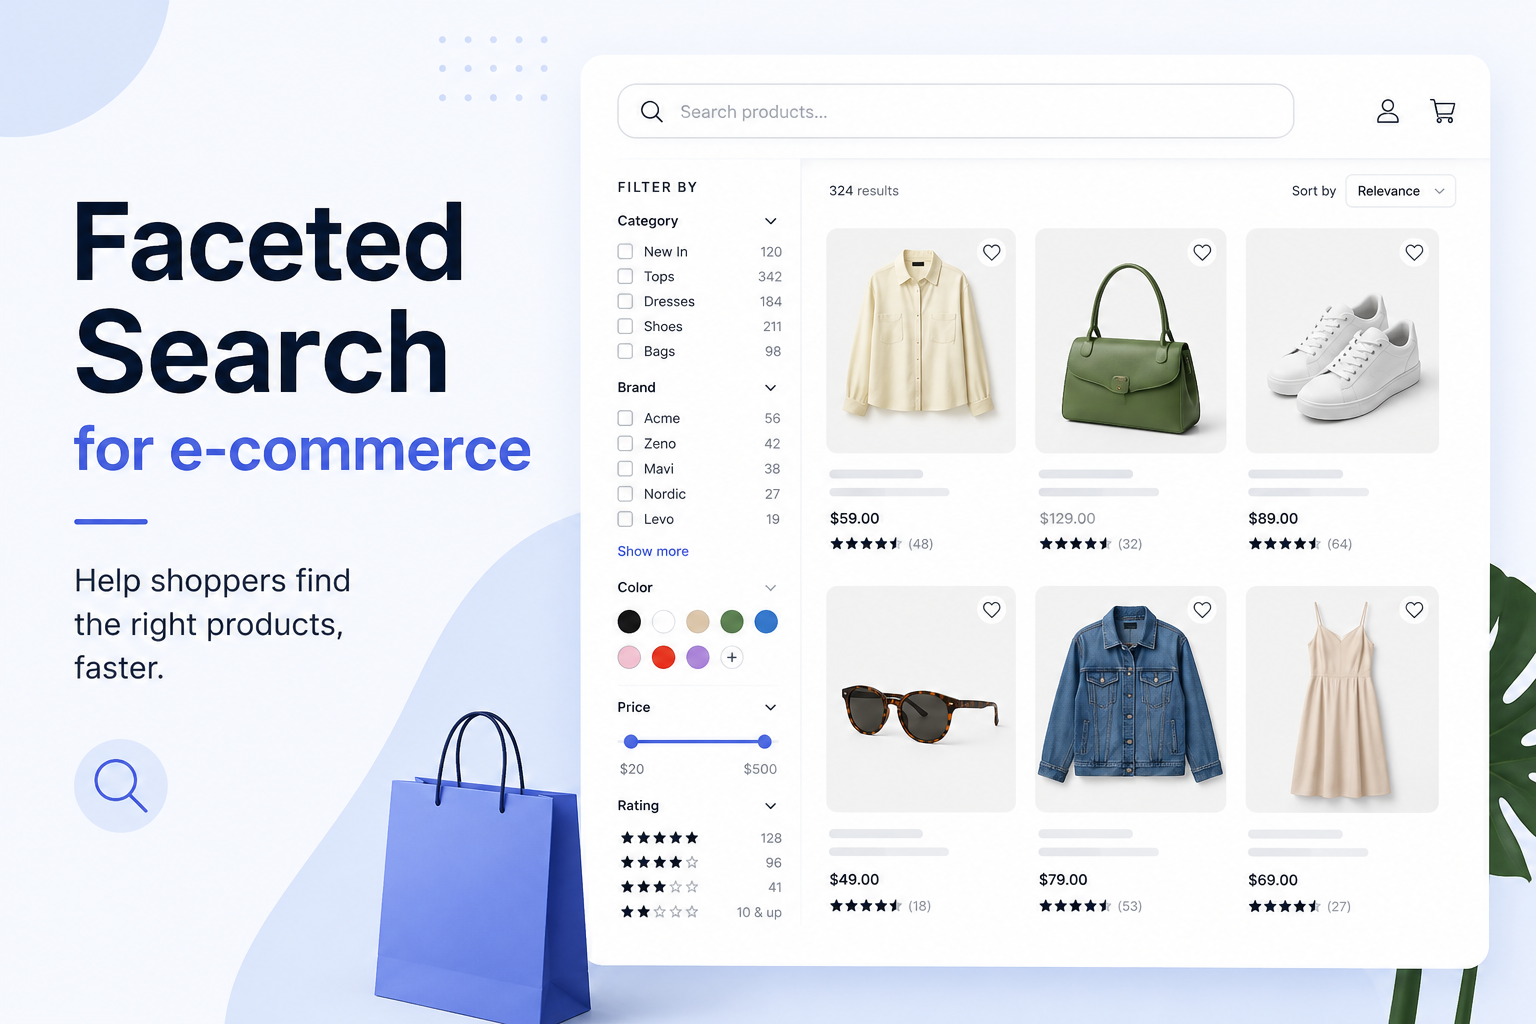
Facets in an online store look simple until the first filter gets applied.
In a catalog, facets are part of navigation. A selected color must not disappear from the list. Neighboring colors are better left available: the user can switch to them or widen the selection. Variants with no products are more useful shown as unavailable right away. Within one facet OR usually applies: red or blue. Across different facets it is AND: brand, color and size at the same time.
The unpleasant part starts after the first selection. Take a product catalog: the user has picked a brand, a color and a size. The main results must stay narrow and show only products matching all three conditions. The filter panel lives by different rules. It has to keep the selected color visible and at the same time show the colors the user can switch to at the same brand and size.
If every facet inherits all filters from the main query, it quickly collapses to the values already selected. If the filters have to be rebuilt by hand for each facet, you end up with separate query branches for color, size, brand, availability, seller and every other attribute.
Manticore Search 25.12.0 added facet_filter_mode, which moves this behavior into the facet API. A query can now describe how the store's filter panel behaves, and the application no longer has to assemble nearly identical queries for each facet by hand.
What an online store's facets need
One answer to the question "how many products have this value?" is not enough for a filter panel. It needs statuses it can work with directly in the interface:
- selected values stay visible and can be cleared quickly;
- neighboring values in the same facet stay available for selection, because they widen the filter through
IN (...); - values in other facets show whether picking them would yield at least one product;
- counts stay predictable: the interface understands what the number refers to — the current results or a wider sample;
- search inside long brand lists, category facets, price ranges, SEO rules and query analytics do not go anywhere; that is a separate part of search design.
facet_filter_mode takes on the most common part of this task: how to recompute the facets after the user has already picked several filters.
What changed
Facets now have three filter inheritance modes:
| Mode | What it does |
|---|---|
strict |
Applies all filters from the main query to the facet. This is the old behavior; it is the default. |
auto |
Applies all filters except the filters on this same facet, and adds status: selected values get selected, neighboring values get available. |
max |
Computes buckets over a wide base sample and adds status to separate selected, available and unavailable values. |
There is also manual control:
ALL FILTERS— apply every filter to the facet;FILTERS color_id, size_id— apply only the listed filters;EXCLUDE FILTERS color_id— apply all filters except the listed ones;ZEROES— starting with Manticore Search 27.3.0, in SQL modemax, keep buckets from the widemaxscope even when theircount(*)in the current facet is0.
In the JSON API the same options are available through facet_filter_mode, mode, filters, exclude_filters and zeroes: true.
In short: strict answers "what is in the current results?", auto answers "what happens if the value of this very filter changes?", and max shows a wide bucket list and adds a status field to the response: selected, available or unavailable.
Minimal example
Take a small catalog. It has a brand, a color, a size and a SKU:
CREATE TABLE products(
  title text,
  brand_id int,
  color_id int,
  color_name string,
  size_id int,
  size_name string,
  sku string
);

INSERT INTO products(id,title,brand_id,color_id,color_name,size_id,size_name,sku) VALUES
(1,'p1',7,1,'red',10,'small','sku1'),
(2,'p2',7,1,'red',20,'large','sku2'),
(3,'p3',7,2,'blue',10,'small','sku3'),
(4,'p4',7,3,'green',30,'xlarge','sku4'),
(5,'p5',8,1,'red',10,'small','sku5'),
(6,'p6',8,4,'black',20,'large','sku6'),
(7,'p7',9,5,'white',10,'small','sku7');
The user has selected:
brand_id=7 AND color_id=1 AND size_id=10
Under these conditions the results contain one product: p1. Let's see what happens to the facets.
strict: the old behavior
With no extra options Manticore uses strict: every facet gets all filters from the main query.
SELECT count(*)
FROM products
WHERE brand_id=7 AND color_id=1 AND size_id=10
LIMIT 0
FACET color_id ORDER BY color_id ASC
FACET size_id ORDER BY size_id ASC;
Response:
+----------+----------+
| color_id | count(*) |
+----------+----------+
|        1 |        1 |
+----------+----------+
+---------+----------+
| size_id | count(*) |
+---------+----------+
|      10 |        1 |
+---------+----------+
auto: a facet ignores its own filter
The auto mode keeps all filters except the filter on the facet that is being computed right now.
SELECT count(*)
FROM products
WHERE brand_id=7 AND color_id=1 AND size_id=10
LIMIT 0
OPTION facet_filter_mode='auto'
FACET color_id ORDER BY color_id ASC
FACET size_id ORDER BY size_id ASC;
Response:
+----------+----------+-----------+
| color_id | count(*) | status    |
+----------+----------+-----------+
|        1 |        1 | selected  |
|        2 |        1 | available |
+----------+----------+-----------+
+---------+----------+-----------+
| size_id | count(*) | status    |
+---------+----------+-----------+
|      10 |        1 | selected  |
|      20 |        1 | available |
+---------+----------+-----------+
What happened:
FACET color_idappliedbrand_id=7 AND size_id=10, but notcolor_id=1;FACET size_idappliedbrand_id=7 AND color_id=1, but notsize_id=10.
This is how the interface gets alternative values without a separate query for each facet. Selected buckets are marked selected, and neighboring values in the same facet are marked available: they can be added to the current filter as a widening through IN (...).
max: a wide bucket list plus status
auto only shows values from the current filter scope for that specific facet. max goes wider: it computes buckets over a base sample and marks their status for the interface separately.
SELECT count(*)
FROM products
WHERE brand_id=7 AND color_id=1 AND size_id=10
LIMIT 0
OPTION facet_filter_mode='max'
FACET color_id ORDER BY color_id ASC
FACET size_id ORDER BY size_id ASC;
Response:
+----------+----------+-----------+
| color_id | count(*) | status    |
+----------+----------+-----------+
|        1 |        3 | selected  |
|        2 |        1 | available |
|        3 |        1 | available |
|        4 |        1 | available |
|        5 |        1 | available |
+----------+----------+-----------+
+---------+----------+-----------+
| size_id | count(*) | status    |
+---------+----------+-----------+
|      10 |        4 | selected  |
|      20 |        2 | available |
|      30 |        1 | available |
+---------+----------+-----------+
status comes straight from Manticore:
selected— the value is already in the filter on this same facet;available— the value can be selected; for neighboring values in the same facet this means widening the filter throughIN (...);unavailable— the value exists in the wide set for the facet, but selecting it would produce no documents under the current filters.
In this example color_id=1 appears in three products of the whole catalog, so under max its count is 3. It is marked selected because it already takes part in the filter. The other colors are marked available: if the user picks one of them, the color filter becomes wider, say color_id IN (1,2). Unavailable values show up where the wide bucket cannot produce documents under the current filter set; the sku example below has such a case.
How to set the filter scope manually
A global facet_filter_mode covers most ordinary cases, but sometimes different facets have to behave differently. For example, keep color strict under all filters, compute size with max, compute SKU from color and size only, and compute brand without the color filter.
SELECT count(*)
FROM products
WHERE brand_id=7 AND color_id=1 AND size_id=10
LIMIT 0
OPTION facet_filter_mode='max'
FACET color_id ALL FILTERS ORDER BY color_id ASC
FACET size_id ORDER BY size_id ASC
FACET sku FILTERS color_id, size_id ORDER BY sku ASC
FACET brand_id EXCLUDE FILTERS color_id ORDER BY brand_id ASC;
Response:
+----------+----------+-----------+
| color_id | count(*) | status    |
+----------+----------+-----------+
|        1 |        1 | selected  |
+----------+----------+-----------+
+---------+----------+-----------+
| size_id | count(*) | status    |
+---------+----------+-----------+
|      10 |        4 | selected  |
|      20 |        2 | available |
|      30 |        1 | available |
+---------+----------+-----------+
+------+----------+-------------+
| sku  | count(*) | status      |
+------+----------+-------------+
| sku1 |        1 | available   |
| sku5 |        1 | unavailable |
+------+----------+-------------+
+----------+----------+----------+
| brand_id | count(*) | status   |
+----------+----------+----------+
|        7 |        2 | selected |
+----------+----------+----------+
How to read this query:
FACET color_id ALL FILTERSapplies all filters and returns only the selected color;FACET size_idinherits themaxmode set at the query level;FACET sku FILTERS color_id, size_idapplies only the color and size filters;FACET brand_id EXCLUDE FILTERS color_idapplies all filters except color.
This mode is needed when one filter panel contains both regular and technical facets, and some values have to be computed under special rules.
ZEROES: zero buckets in max
ZEROES is for when counts must stay strict but the value list stays wide. It works together with max: through OPTION facet_filter_mode='max' or through MODE max on a specific facet.
Without ZEROES a facet with ALL FILTERS shows only the bucket that passed every filter:
SELECT count(*)
FROM products
WHERE brand_id=7 AND color_id=1 AND size_id=10
LIMIT 0
OPTION facet_filter_mode='max'
FACET size_id ALL FILTERS ORDER BY size_id ASC;
Response:
+---------+----------+----------+
| size_id | count(*) | status   |
+---------+----------+----------+
|      10 |        1 | selected |
+---------+----------+----------+
Add ZEROES and Manticore keeps the same visible counts, but returns the remaining buckets from the wide max scope with a zero count:
SELECT count(*)
FROM products
WHERE brand_id=7 AND color_id=1 AND size_id=10
LIMIT 0
OPTION facet_filter_mode='max'
FACET size_id ALL FILTERS ZEROES ORDER BY size_id ASC;
Response:
+---------+----------+-----------+
| size_id | count(*) | status    |
+---------+----------+-----------+
|      10 |        1 | selected  |
|      20 |        0 | available |
|      30 |        0 | available |
+---------+----------+-----------+
This lets the interface show large and xlarge next to the selected small: the number refers to the current strict result set, while status shows that these values can still be picked as a filter widening.
The same thing through the JSON API
SQL is shorter here and shows the mechanics better, but the JSON API supports the same approach:
POST /search
{
  "table": "products",
  "limit": 0,
  "query": {
    "bool": {
      "must": [
        { "equals": { "brand_id": 7 } },
        { "equals": { "color_id": 1 } },
        { "equals": { "size_id": 10 } }
      ]
    }
  },
  "facet_filter_mode": "max",
  "aggs": {
    "colors": {
      "terms": { "field": "color_id", "size": 10 },
      "sort": [ { "color_id": { "order": "asc" } } ]
    },
    "sizes": {
      "terms": { "field": "size_id", "size": 10 },
      "sort": [ { "size_id": { "order": "asc" } } ]
    }
  }
}
Response:
{
  "took": 0,
  "timed_out": false,
  "hits": {
    "total": 1,
    "total_relation": "eq",
    "hits": []
  },
  "aggregations": {
    "colors": {
      "buckets": [
        { "key": 1, "doc_count": 3, "status": "selected" },
        { "key": 2, "doc_count": 1, "status": "available" },
        { "key": 3, "doc_count": 1, "status": "available" },
        { "key": 4, "doc_count": 1, "status": "available" },
        { "key": 5, "doc_count": 1, "status": "available" }
      ]
    },
    "sizes": {
      "buckets": [
        { "key": 10, "doc_count": 4, "status": "selected" },
        { "key": 20, "doc_count": 2, "status": "available" },
        { "key": 30, "doc_count": 1, "status": "available" }
      ]
    }
  }
}
How this differs from Meilisearch, Elasticsearch and OpenSearch
The same scenario was run against Manticore, Meilisearch, Elasticsearch and OpenSearch: the filters brand_id=7, color_id=1, size_id=10 are active; the results stay strict, and the facets have to show the variants that appear when a facet's own filter is excluded.
| Engine | Excluding the facet's own filter in one query | Native bucket status | What is left to the application |
|---|---|---|---|
| Manticore | Yes, through auto/max |
Yes, in auto/max; unavailable only in max |
Rendering the interface, SEO, analytics and custom rules. |
| Meilisearch | Not in this form | No | Issue extra requests and assemble facets on the application side. |
| OpenSearch | Yes, but manually through global + filter aggregations |
No | Duplicate the filter branches and compute status yourself. |
| Elasticsearch | Yes, but manually through global + filter aggregations |
No | The same: maintain separate aggregation branches and client-side logic. |
In Meilisearch basic facets are easy to use, but a query like:
{
  "filter": ["brand_id = 7", "color_id = 1", "size_id = 10"],
  "facets": ["color_id", "size_id"]
}
returns counts for the already filtered results. In this dataset that is only color_id=1 and size_id=10. The alternatives color_id=2 and size_id=20 do not appear in such a response. If the interface needs them, you have to issue extra requests and merge the results in the application.
In Elasticsearch and OpenSearch the same mechanics can be assembled in one query, but each facet needs an explicitly set separate aggregation branch. For color you keep brand_id and size_id, for size you keep brand_id and color_id, and so on. It works, but the query grows fast, and the bucket statuses are still computed on the application side.
The main difference is where this logic lives. In Manticore it is set directly in the facet API; in the other systems it is usually assembled out of several similar filter trees.
Performance and limits
strict stays the default and keeps the old behavior. If you only need facets inside the current results, change nothing.
auto usually fits online store filters better: it shows alternative values inside each facet, marks the selected values selected and the neighboring ones available.
max is worth turning on when the interface needs value lists wider than the current results and unavailable variants. This mode costs more: Manticore computes the buckets in a wide scope and then determines their status separately. On large datasets and with many facets, that adds up.
There are limits as well:
- local filter rewriting for a facet supports only attribute filters joined with
AND; - complex
AND/ORtrees for individual facets are not rewritten automatically; - already-selected values are currently matched reliably only for explicit value filters like
=andIN; - for ranges like price, this status is not computed automatically yet.
For price, discounts and ratings it is better to define explicit separate ranges. For example, keep the numeric field for sorting and the slider, and add price_band or discount_band for the facet. Then the interface can show clear statuses for ready-made ranges.
SEO for facet URLs, A/B tests, merchandising rules and query analytics remain tasks of the application or the platform around search.
In practice, start with auto if you need alternative values, and move to max when the interface has to show a wide bucket list with the selected, available and unavailable statuses.
Further reading
If you need an introductory walkthrough of faceted search in Manticore, start with the older post Faceted search. It covers the basic FACET, sorting, limits and facets on expressions.
Details on FACET are in the documentation.
For an interactive introduction to facets, take the Manticore Faceting course.